CloudWalk Technology Wins ICCV 2023 Fine-Grained Behavior Detection Challenge Champion, Building a Multimodal Technology Closed Loop
Recently, the ICCV 2023 Open Fine Grained Activity Detection Challenge concluded successfully, and CloudWalk Technology won the championship in the behavior classification track (hereinafter referred to as OpenFAD23-ICCV23).
In the challenge, CloudWalk's CongRong Large Model demonstrated excellent understanding and processing capabilities for various modal information, standing out from many well-known domestic and international enterprises and research institutions such as Waseda University and SoftBank, setting a new world record, and once again showcasing CloudWalk Technology's technical strength in the field of multimodal large models.
Table 1: CloudWalk Technology's performance on the OpenFAD23-ICCV23 dataset
Focusing on Leading Technology R&D to Promote the Application of Visual Large Models
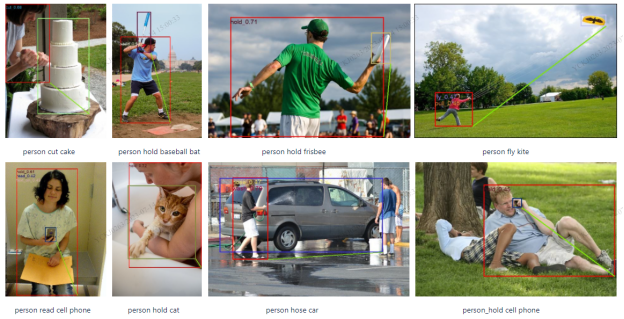
Compared to 2D image recognition, 3D behavior recognition technology adds temporal dimension modeling and is an important component of human-centric perception tasks, always being a research hotspot in the field of artificial intelligence.
Large models have powerful representation capabilities and have been validated in multiple modalities (such as language, audio, image, video, visual language). CloudWalk, based on actual business deployment needs, has developed a 3D behavior recognition foundational large model based on spatiotemporal modeling.
This model is designed based on the Vision Transformer structure, fully correlating spatial and temporal information through a self-attention mechanism.
In the pre-training phase, self-supervised learning is performed using masked reconstruction. To enable the model to learn both scene semantics and temporal actions, scene-biased multimodal semantic features and action-biased temporal features are simultaneously used as teacher models for multi-branch feature distillation, allowing the model to have both scene semantic and temporal action understanding capabilities.
The basic spatiotemporal features obtained from large model pre-training can be widely used in downstream tasks such as video retrieval, video question answering, 3D behavior recognition, and behavior keyframe detection. In the fine-tuning stage of downstream tasks, redundant parts of the model are adaptively removed through inter-frame information complementation, greatly improving the training and inference speed of downstream tasks.
Table 2: CloudWalk Technology's performance on the authoritative 3D behavior recognition dataset Something-Something V2
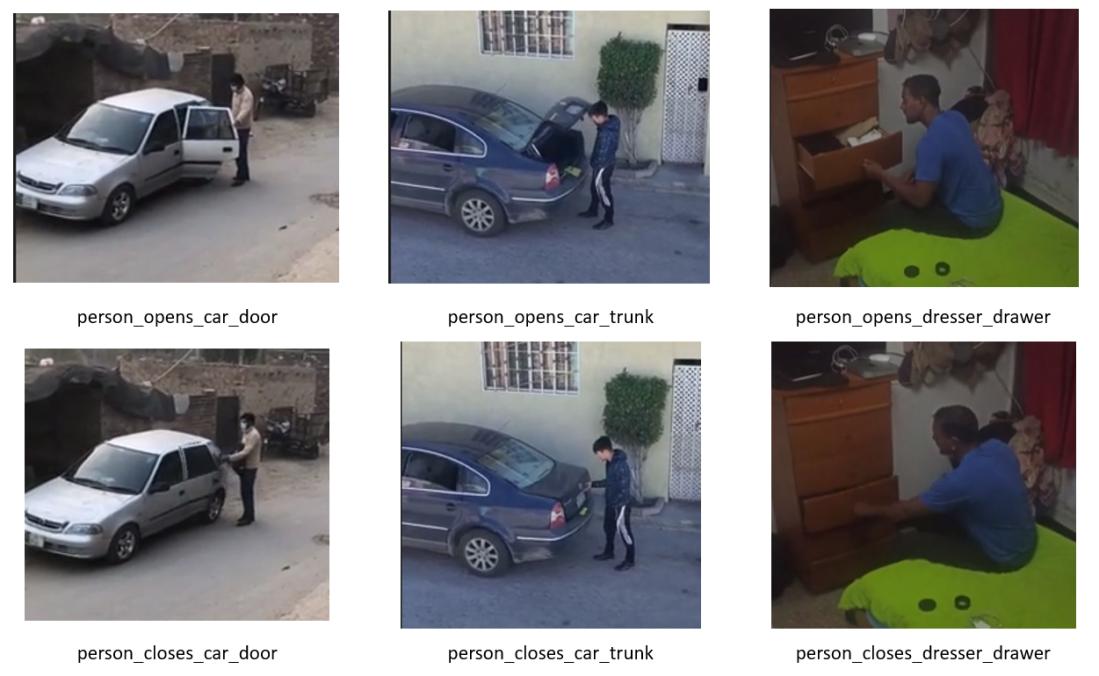
The OpenFAD23-ICCV23 dataset contains 491 human behaviors in daily life, some of which have only extremely subtle differences. It requires extracting multiple frames from videos and analyzing them using 3D spatiotemporal modeling algorithms.
Leveraging its deep accumulation in the visual field, CloudWalk Technology's CongRong Large Model achieved an accuracy of 93.87% on coarse behavior categories and 91.96% on fine-grained behavior categories on the OpenFAD23-ICCV23 dataset, with recognition accuracy more than 4% higher than the champion solution of the previous OpenFAD22.
The significant improvement in accuracy demonstrates the advantages of large models in modeling spatiotemporal relationships, indicating that 3D behavior recognition algorithms have entered the multimodallarge model era, which will greatly enhance the commercial application value of this technology. Currently, this technology has been widely applied in fields such as finance and security, for example, personnel action compliance recognition, and detection of behaviors like fighting and falling.
Repeatedly Setting Records to Build a Closed Loop of Multimodal Large Model Technology
Since the beginning of this year, CloudWalk Technology has repeatedly achieved technological breakthroughs in the multimodal field.
In June
, CloudWalk proposed a self-supervised learning method for visual large models at CVPR 2023, achieving the same effect with only 1% of the previous data volume or even without real data.
In July
, CloudWalk's pedestrian foundational large model became world number one on four datasets: PA-100K, RAP V2, PETA, and HICO-DET, and its product foundational large model set new world records on MUGE and Product1M, the two largest open-source Chinese multimodal product retrieval datasets.
In August
, CloudWalk's unified vision-language tracking model set four world records on four challenging cross-modal datasets (TNL2K, LaSOT, LaSOTExt, WebUAV-3M).
This enables the CongRong Large Model to be applied with better interactive performance in industries such as finance, security, government affairs, transportation, energy, education, healthcare, and entertainment.
So what does multimodality really mean?
When you input a photo and use voice or text to "command" the AI to partially edit it and send it to a friend, it can immediately understand and complete the instruction.
Multimodal interaction lowers the barrier to using AI, making it possible for AI to become a production tool and personal assistant for millions of people.
Today, multimodal large models have become the next frontier for large models moving towards the goal of Artificial General Intelligence (AGI). CloudWalk Technology continues to focus on multimodal technology research and development, promoting the integration of vision, language, audio, and other technologies, bringing innovation and transformation to more industries.
You May Be Interested In
-
 2023-09-21
Recently, the ICCV 2023 Open Fine Grained Activity Detection Challenge concluded successfully, and CloudWalk Technology won the championship in the behavior classification track (hereinafter referred to as OpenFAD23-ICCV23).
-
 2023-07-19
CloudWalk Technology has made significant progress in visual large models. Its pedestrian foundation model stood out from Alibaba, Hitachi, and many other well-known universities, enterprises, and research institutions on four datasets—PA-100K, RAP V2, PETA, and HICO-DET—setting new world records.
-
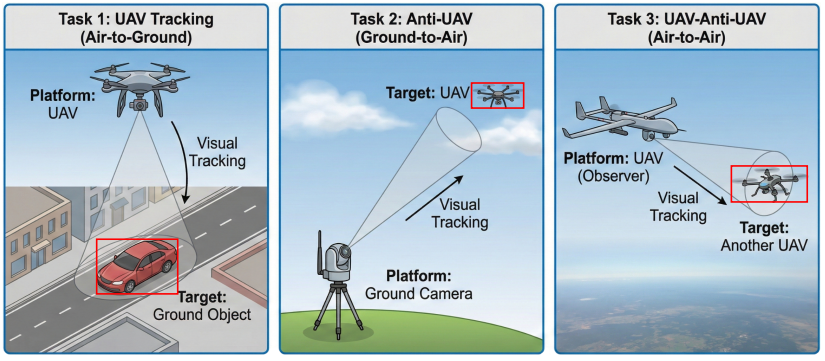 2025-12-12
When both the tracker and the target are flying at low altitude and high speed, can traditional visual tracking algorithms keep up? Recently, a joint research team from CloudWalk Technology, Shanghai Jiao Tong University, Hong Kong University of Science and Technology (Guangzhou), Sun Yat-sen University, and the Institute of Information Engineering, Chinese Academy of Sciences released a hardcore work—UAV-Anti-UAV. This is the industry's first million-level multimodal anti-UAV visual tracking benchmark for "Air-to-Air" scenarios, and proposes a powerful Mamba-based baseline, MambaSTS. MambaSTS achieves the best performance on all five metrics of the UAV-Anti-UAV benchmark. This is another technological breakthrough by CloudWalk Technology in multimodal large models. Facing dual dynamic interference, how does the current SOTA perform? Let's find out!